
Cut AI costs with models built for the task
SIE serves small open models for everyday AI tasks. Find a model that meets your quality target, then call our API or run it in your own cloud.
Keep inference inside your own network
your deployment.
- Setup
- Example private-cloud deployment
- Owner
- Your platform team
-
Where do model requests run?
On SIE workers in the cloud account and region you choose.
-
Who can call the models?
Your applications, through access rules you configure.
-
What does an offline deployment need?
Mirrored images and model files, with telemetry turned off.
-
Who owns the deployment?
Your team. Superlinked support is optional.
Bring your configuration to the security review In your control
Better search than Cohere and OpenAI, 3 to 15 times faster
Run these document jobs 88% cheaper
- Documents to JSON
$7,680$728 More values exactly right - PDF pages searched
$740$200 Ranking quality: 64.0 vs 64.8 nDCG@10
Total $8,420 $928
Call our API, or run the same models in your own clusters
Serverless API
Task-specific models behind one API, with usage-based pricing.
- No GPUs to run or keep busy
- Usage pricing, no idle GPU bill
- SOC 2 Type 2, US or EU data
- Same SDK and model IDs in your cluster
Run locally
The open-source server, free on your laptop or a GPU VM.
- Apache-2.0, the engine behind both
- NVIDIA GPU or Apple Silicon
- Same SDK and model IDs as the API
- Offline; data stays on your machine
Native Inference
Run SIE Cluster in your own cloud, with our engineers helping your team evaluate models and operate the deployment.
Learn how teams run small open models in production
Most AI tasks no longer need a frontier model
Read article
Sharing GPUs between models: SIE vs HAMi, MIG and Run:ai
Read article
Small Models Decide What Reaches Your Search LLM
Read article
Run topk-embed-v1 at 50k tokens/s on a single GPU
Read article
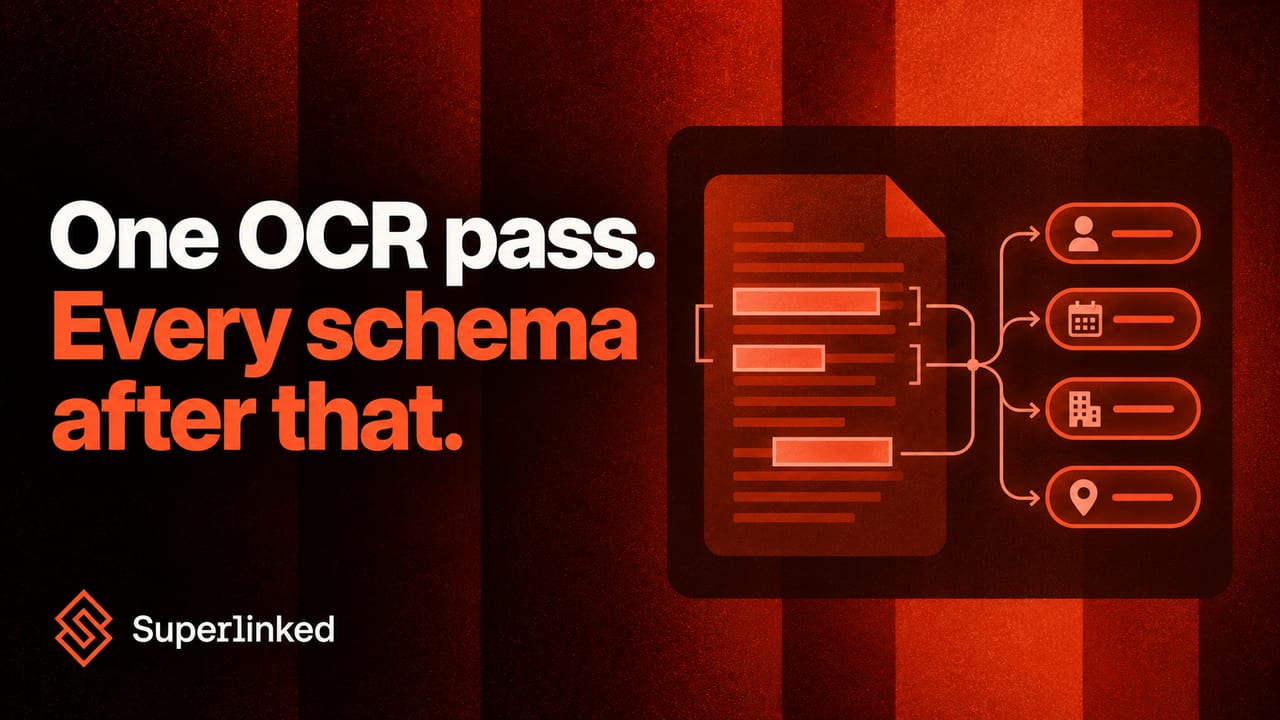
Most AI Document Demos Stop Before the Hard Part
Read article
FlashNorm: How Weight Folding and CUDA Streams Make RMSNorm Faster
Read article
Start from your task or your industry
Search and RAG
Documents
Text and LLM apps
Images and audio
Safety and compliance
Industries